How to Automate Preventive Maintenance Schedules
 By Steven Quayle
Most maintenance teams do not have a scheduling problem. They have a memory problem. The quarterly inspection on the rooftop unit happens when somebody remembers it, the pump rebuild slips by six weeks because the person tracking it was on leave, and the spreadsheet holding all of it gets updated by whoever last had the file open.
Automating the schedule moves that memory into a system that generates the work order on its own, at the right time, with the right checklist, whether or not anyone is thinking about it. The mechanics are straightforward. Getting them right on the first pass is what stops the team from quietly ignoring the schedule by month two.
Pick a trigger type for each asset
The trigger is the rule that decides when the next work order appears. The four types below differ by what the preventive maintenance system is counting: a calendar date, the gap since the last completion, a usage meter, or a measured condition. Choosing the wrong one for an asset is what pulls a schedule out of step with the equipment it is supposed to protect.
Fixed calendar dates
A fixed trigger fires on set dates regardless of what happened last time: the first week of every quarter, the same week each year, every 30 days from a start date. Use it where an outside date drives the work rather than the equipment: statutory inspections, insurance-required checks, fire system tests, and anything an auditor will ask for on a fixed cadence. (Those requirements vary by country and often by local jurisdiction, so confirm what applies where you operate.) The advantage is predictability. The drawback is that a missed occurrence stays missed, and the next one still fires on its original date.
Floating intervals that count from the last completion
A floating trigger measures from the day the last work order was closed rather than from a calendar grid. Close the 90 day service eleven days late and the next one falls due 90 days after that closing date. This is the right default for most mechanical servicing, because the clock that matters is time since the machine was actually serviced. It also keeps the schedule from bunching: on a fixed trigger, a late job and its successor can land in the same week. The tradeoffs between the two are covered in more depth in our guide to time-based preventive maintenance.
Meter and runtime readings
Anything that wears by use rather than by time belongs on a meter trigger: engine hours, kilometers, cycles, production counts, pump running hours. A van covering 4,000 km a month and one covering 400 should not share a service interval, and a calendar trigger gives them one. Meter triggers need a reading to fire, which makes them the most fragile type to automate. More on that below.
Condition thresholds
A condition trigger fires when a measured value crosses a limit: vibration velocity above a set figure, a bearing running hotter than ambient by a defined margin, insulation resistance below a floor. These are the most efficient triggers, because the work happens when the asset asks for it, and the most demanding, because somebody has to collect the readings on a route or wire up sensors that do it automatically. Condition triggers are worth adding to a handful of critical machines once the time and meter based schedule is running and somebody is already walking a route. Thermal imaging is a common first step, and the automation is only ever as good as the inspection data feeding it.
A real site ends up mixed. Floating intervals carry most of the building equipment, meters carry the vehicles and the high-use rotating machinery, fixed dates carry the compliance work, and a small group of critical assets carry condition triggers.
Set the interval from two sources, never one
The manufacturer interval was written by somebody who has never seen your site. It assumes a duty cycle, an operating environment and a load profile that may be nothing like yours. Your own repair history is the correction, and the two together give you an interval you can defend.
Work in this order:
Take the manufacturer figure for the asset class as your opening number.
Pull every work order raised against that asset, or against the class if a single asset is too thin, for the last two or three years. Split them into planned and unplanned.
Look at where the unplanned repairs sit relative to the planned visits. Failures clustering in the last third of the interval mean the interval is too long. No findings at all, cycle after cycle, mean it is probably too short.
Move in one direction at a time, by no more than about a quarter of the current interval, and only after two clean cycles at the current setting.
A worked example. An air handling unit on a 90 day filter and belt PM produced no findings on six consecutive visits and no unplanned calls in eighteen months. Stretching it to 120 days removes one visit per unit per year. Across forty units at 45 minutes each, that is 30 labor hours returned annually, and the schedule still catches a filter before it loads up. Run the longer interval for two full cycles, check the unplanned call log against those units, then decide whether to stretch it again.
Consequence decides which way you round. Where a failure stops production, injures somebody or closes a building, round down and accept the extra visits. Where a failure means a comfort complaint or a machine sitting idle for a day, round up. A criticality ranking is what turns this into a decision rather than an argument, which is why setting up the asset hierarchy belongs before the schedule rather than after it.
Build lead time into the trigger
A work order that appears on the morning it is due is already late. The parts are not staged, the technician's day is planned, and a vendor who has to attend needs notice. Every automated PM needs a generation date that sits ahead of its due date, and the gap is a setting you choose per asset rather than a site-wide default.
Set it from the longest thing that has to happen before work can start. If a filter set takes five working days to arrive and the team plans its week at a fixed planning meeting, fourteen days ahead of the due date is the floor. For a contractor visit booked through a vendor, three or four weeks is closer. An asset with parts on the shelf and nothing to coordinate is fine at two or three days.
Decide separately what should happen when the previous occurrence has not been closed. There are two behaviors to choose between: generate the next one regardless, or hold it until the open one is finished. Holding is the safer default on floating triggers, because the alternative is two open copies of the same job and a technician picking one. On fixed compliance triggers, generate anyway: the missed occurrence is a record you want visible in the work order history, not one you want suppressed.
Stagger the first rollout, or the team will ignore it
An interval set slightly wrong costs a few unnecessary visits. A rollout that lands all at once costs the schedule itself. A team loads 260 assets into a new system over a fortnight, sets every PM to start today, and the scheduler produces several hundred work orders in week one. Nothing in that list is wrong. The team will still stop reading it, because a backlog that size registers as noise rather than as work, and a list you cannot finish is a list you stop opening.
Spread the start dates across one full interval cycle. For a group of assets on a 90 day PM, distribute their last completion dates across the previous 90 days so the first generated occurrences land evenly through the coming quarter instead of all on day one. Where the import accepts a last completed date or a first due date per asset, that single field is what does the work. Filling it in with today's date for every row is the mistake, and it takes about the same amount of effort to fill it in properly.
Size the spread against labor rather than against the calendar. Three technicians with 30 usable wrench hours each give you 90 hours a week. Planned work should occupy somewhere between half and two thirds of that, leaving room for the reactive work that arrives whatever you planned. So the schedule for that team wants to generate roughly 45 to 60 hours a week. If the estimated durations on your PMs add up to more than that, either the intervals are too tight or the scope of each visit is too large, and you have found that out before the team did.
Load the highest consequence assets first and let them run for a full cycle before adding the next group. Plan for three or four waves. On a 90 day PM, that puts the last group live inside a year. What the team sees each week is a list it can actually finish, which is what builds the habit of working from the list at all.
Make each automated PM return data
A schedule that generates bare work orders titled "Monthly service" produces closed records that prove nothing. The interval review described above needs findings, and findings only exist if the work order asks for them. Build the template once, and every future occurrence inherits it.
A step by step checklist instead of a free text box. Steps get completed. Paragraphs get skipped.
A pass or fail against each step, with a note required on any fail.
A reading captured on every step that measures something: pressure, temperature, thickness, current draw. A number recorded across twelve cycles is a trend. A tick is nothing.
Parts consumed booked against the work order rather than taken off the shelf quietly, so consumption history can tell you what to stock.
A meter reading at every visit on metered assets, which keeps the next trigger accurate as a side effect of doing the job.
The point of all of it is that next quarter you can answer a specific question: on this asset, across the last six services, what did we find? That answer is what lets you change an interval with confidence instead of moving it because somebody complained. Our preventive maintenance features page shows what these templates look like in practice.
The four ways an automated schedule stops being used
Low criticality assets scheduled like critical ones
A monthly check on a store room extractor fan occupies the same slot in the list as a monthly check on the main chiller, and the technician knows the difference even when the schedule does not. Once a third of the weekly list is work nobody believes in, the credibility of the other two thirds goes with it. Push low consequence assets out to the longest interval you can defend, or take them off the schedule entirely and pick them up on a walk-around route.
Meter triggers with no readings arriving
A meter trigger that never receives a reading never fires, and unlike a missed calendar date, nothing on the screen looks wrong. The asset simply goes quiet. Either the reading is captured by something that already happens (the driver logs the odometer at fuel-up, the operator records hours at shift handover, telematics pushes it in automatically) or that asset belongs on a time trigger instead. Within the first month, list every metered asset whose newest reading is older than 30 days and convert them.
PMs closed without completion data
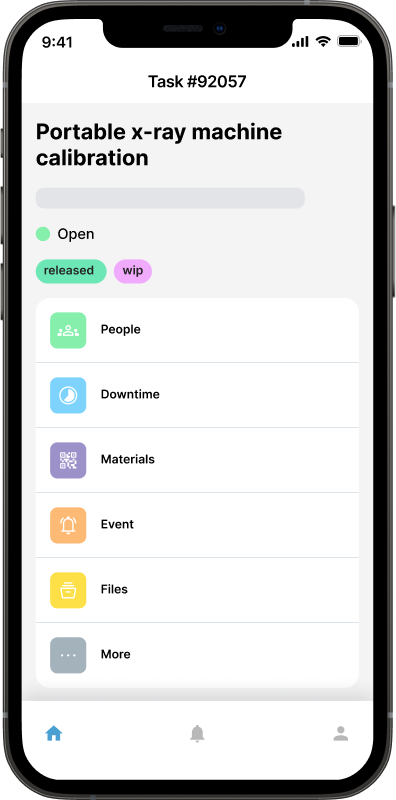
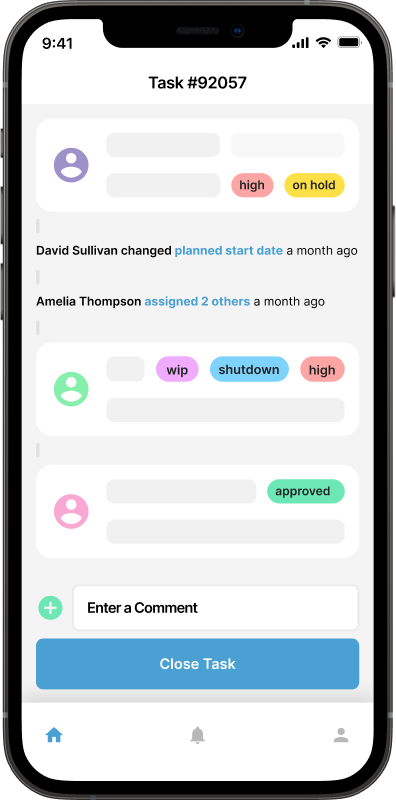
A technician closing eight work orders from the truck at the end of the day is giving you eight timestamps and nothing else. The fix is structural rather than cultural: require the data at the step level so the work order cannot close without it, and sample a handful each month to see what is actually being recorded. This is also the strongest argument for doing the work on a phone at the asset, because data entered an hour later from memory is data you should not base an interval change on.
A schedule nobody owns
Automation removes the remembering. It does not remove the deciding. Somebody still has to approve interval changes, retire PMs on equipment that was sold, and add PMs on equipment that arrived last month. Without a named owner the schedule ages quietly, and a year later it is generating work against a compressor that left the building.
What to review every quarter
Put 40 minutes in the calendar once a quarter and go through six things:
On-time PM completion rate. Sitting below about 80 percent usually means the schedule is generating more work than the team can absorb, not that the team is slow.
Planned versus unplanned hours, read as a trend rather than as a single figure. The line should be moving toward planned.
PMs with no findings across three or more consecutive cycles. These are your candidates for a longer interval.
Assets with unplanned repairs falling between scheduled visits. These need a shorter interval, a different trigger type, or a wider checklist.
Metered assets whose last reading is stale.
PMs still generating against assets that no longer exist.
The first two are the ones worth charting, because they move slowly and tell you whether the program is working at all. There is more on choosing what to track in our guide to CMMS metrics that indicate asset health.
Where to start this week
Take the ten assets whose failure would cost you the most, in downtime, in safety exposure or in replacement cost. Put each one on the trigger type that matches how it actually wears, set an interval you can point at evidence for, add a lead time long enough to stage the parts, and write a checklist that captures numbers rather than ticks. Run those ten for one complete cycle before you load the next group.
Ten automated PMs that get completed and recorded are worth more than three hundred that generate on time and get closed without being read.
Further Reading
How can preventive maintenance software help large vehicle fleets?
The modern economy consists of millions of companies of all sizes. For many of these firms, operating a large vehicle fleet is a key part of how they get day-to-day tasks done. This often requires fleets of cars, vans, trucks, service equipment and heavy machinery.
Read more →
How CMMS Software Boosts Preventive Maintenance Strategies
By integrating advanced technology with maintenance operations, CMMS platforms have become indispensable tools for optimizing asset management and ensuring operational continuity.
Read more →
Video: Create Preventive Maintenance Tutorial
Learn how to streamline your preventive maintenance (PM) process in Maintainly CMMS using task templates and automations. In this step-by-step walkthrough, we’ll show you how to set up recurring work orders, with standardized preventative maintenance procedures, and ensure every asset is serviced on time, without the hassle of manual scheduling.
Read more →